TL;DR

Get everyday helpers delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
In a dermatologist-reported test of 200 biopsy-confirmed skin lesions, a fine-tuned Inception v3 convolutional neural network correctly named 125 diagnoses, compared with 84 and 85 for two large language models. The small, single-dataset comparison does not establish how the systems would perform in clinical practice or across broader patient groups.
A dermatologist’s test of 200 biopsy-confirmed skin lesions found that a fine-tuned, roughly 10-year-old convolutional neural network identified the correct diagnosis more often than two frontier large language models: 62% versus 42% and 42%. The result, reported by the dermatologist on lynchlab.net, is a limited comparison rather than evidence that the CNN is ready to guide patient care.
The comparison used GPT-6 Astra, Claude Fable 5.1 and a fine-tuned version of Inception v3, a CNN first published by Google in 2015. The dermatologist said the two language models each named the correct diagnosis for fewer than half of the 200 lesions: Astra got 84 right, and Fable 5.1 got 85. The CNN correctly classified 125.
The sample was drawn at random from MILK10k, a public dataset released through the International Skin Imaging Collaboration in 2025, according to the report. Each lesion had a clinical photograph and a dermoscopic image. The test included six diagnosis categories: 30 melanomas, 25 basal cell carcinomas, 25 squamous cell carcinomas, 20 actinic keratoses, 50 benign moles and 50 seborrhoeic keratoses. All 200 diagnoses had been confirmed by histopathology.
The models received both images and were asked to select a likely diagnosis from the same six options, or say they were unsure, and to state whether the lesion could be discharged, needed follow-up or required biopsy. The report says neither LLM declined a case. In one example, both LLMs called an invasive melanoma on the ear a harmless seborrhoeic keratosis and said the patient could be discharged; the CNN identified melanoma from the dermoscopic image.
A Warning About Image-Based Diagnosis
The result challenges the assumption that a newer, more general-purpose AI model will necessarily outperform a smaller system tailored to a specific image task. Here, the specialized CNN had been fine-tuned on dermatology images, while the LLMs were asked to interpret images with a text prompt. The comparison suggests that model design and training data may matter as much as a model’s general capabilities.
The safety stakes are clearest in the melanoma example: a mistaken benign label paired with a discharge recommendation could delay further assessment. But the test measured performance on a small, selected set of images, not patient outcomes or clinical decision-making. It cannot establish how often any model would miss cancer in routine care, nor whether these results hold for different cameras, skin tones, clinical settings or patient populations.
The report also says the CNN can run in a phone browser and that images are not uploaded when using its demonstration. That may make the model easy to try, but availability is not clinical validation. None of the reported scores alone supports using an AI output in place of assessment by a qualified clinician.
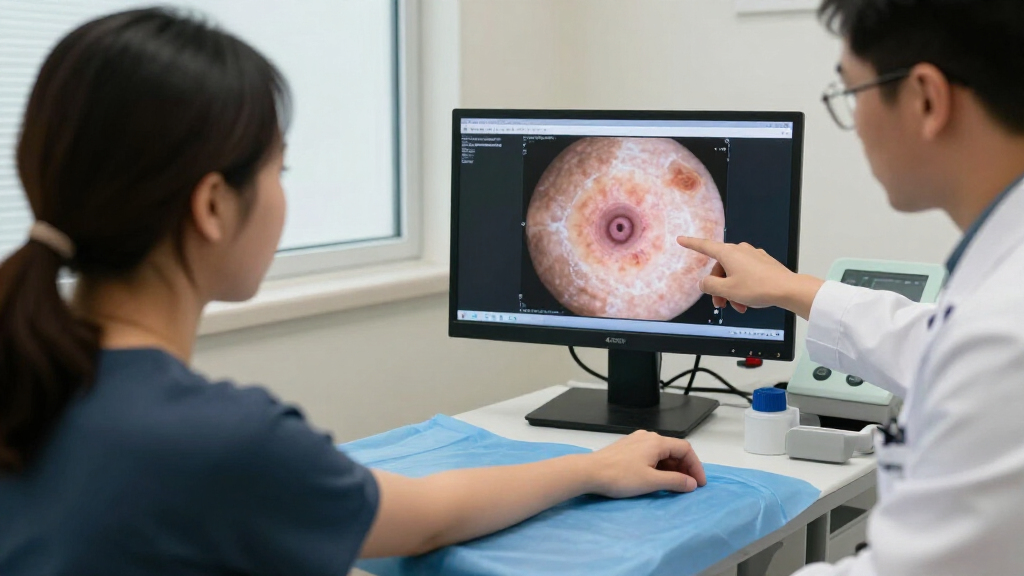
dermatoscope for skin lesion examination
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
How the Three Systems Were Tested
The CNN was trained on 68,011 clinical and dermoscopic images from the ISIC Archive, according to the dermatologist. Inception v3 had been pretrained on everyday photographs, then fine-tuned across all layers on a single H100 GPU. The report says this fine-tuning took about 20 minutes.
The author states that the 200 test lesions, along with other photographs of the same lesions or patients, were excluded from training and validation. The test cases were also not used to choose the model or set its threshold. For each lesion, the CNN scored both images and combined them, assigning most of the weight to the dermoscopic view. The LLMs received the same two images and the same prompt at default settings.
The sample included only lesions that had been biopsied, including the benign ones. The author notes that this makes the benign cases a selected group: a mole that a clinician chose to remove may be more concerning or difficult to classify than an ordinary mole encountered in a general population. The reported accuracy is therefore specific to this test set, not a direct estimate of performance across all skin lesions.
“A ten-year-old network, fine-tuned for about twenty minutes, beat both of them at recognising skin cancer.”
— The dermatologist who conducted the test, writing on lynchlab.net
Limits of the 200-Lesion Sample
The report describes a single 200-lesion test; it does not provide evidence of a larger, independent replication or a prospective clinical trial. It is not clear from the reported material whether other researchers have reviewed the analysis, whether the full test protocol and data are available for independent reproduction, or how the systems would perform on images collected outside the dataset.
The findings also do not establish that one system is broadly better at skin cancer diagnosis. Scores differed by category: Astra identified all 25 basal cell carcinomas in this sample, while the CNN identified 24; the CNN did better on melanoma, squamous cell carcinoma, moles and seborrhoeic keratoses. No patient outcomes were measured, and the report does not establish how a model’s confidence or discharge recommendation would affect decisions in practice.
The article’s stated timing places the tested LLMs among models available in October 2026. Independent confirmation of the comparison and further information about evaluation conditions would help clarify how far the result can be generalized.
Independent Testing Is the Next Step
The report does not announce a follow-up study or a planned clinical deployment. The next useful step would be independent testing on larger, varied datasets, with a prespecified protocol and cases from settings beyond the training archive. Such work could assess performance across image sources and patient groups, as well as how often the systems recommend discharge when additional assessment is warranted.
Before any clinical use, researchers and health authorities would also need evidence about how these tools perform alongside clinicians, how errors are handled and whether their recommendations improve care. Until then, the reported scores should be read as an early comparison on one selected sample, not as a basis for self-diagnosis or a substitute for professional evaluation.
Key Questions
Which system scored highest in the test?
The fine-tuned Inception v3 CNN correctly named 125 of 200 lesions, or 62%. GPT-6 Astra got 84 right and Claude Fable 5.1 got 85, each reported as 42%.
Does this prove older AI is better for diagnosing skin cancer?
No. The report compares three systems on one sample of 200 biopsied lesions. It does not establish performance across other datasets, clinical settings or patient populations.
Did the models miss melanomas?
Yes. Among the 30 melanomas in the sample, the report says Astra identified 8, Fable 5.1 identified 11, and the CNN identified 13. The figures describe this test set only, not general clinical performance.
Were the systems tested in a clinic?
No clinical trial is described. The systems were given images from a public dataset and asked to classify the lesions and state whether they could be discharged, followed up or biopsied.
Can patients use the CNN to decide whether a lesion is cancer?
The report describes a browser-based demonstration, but it does not establish the CNN as a clinical diagnostic tool. People concerned about a skin lesion should seek assessment from a qualified health professional rather than rely on an AI result.
Source: hn
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.